← All work
Research Paper Assistant
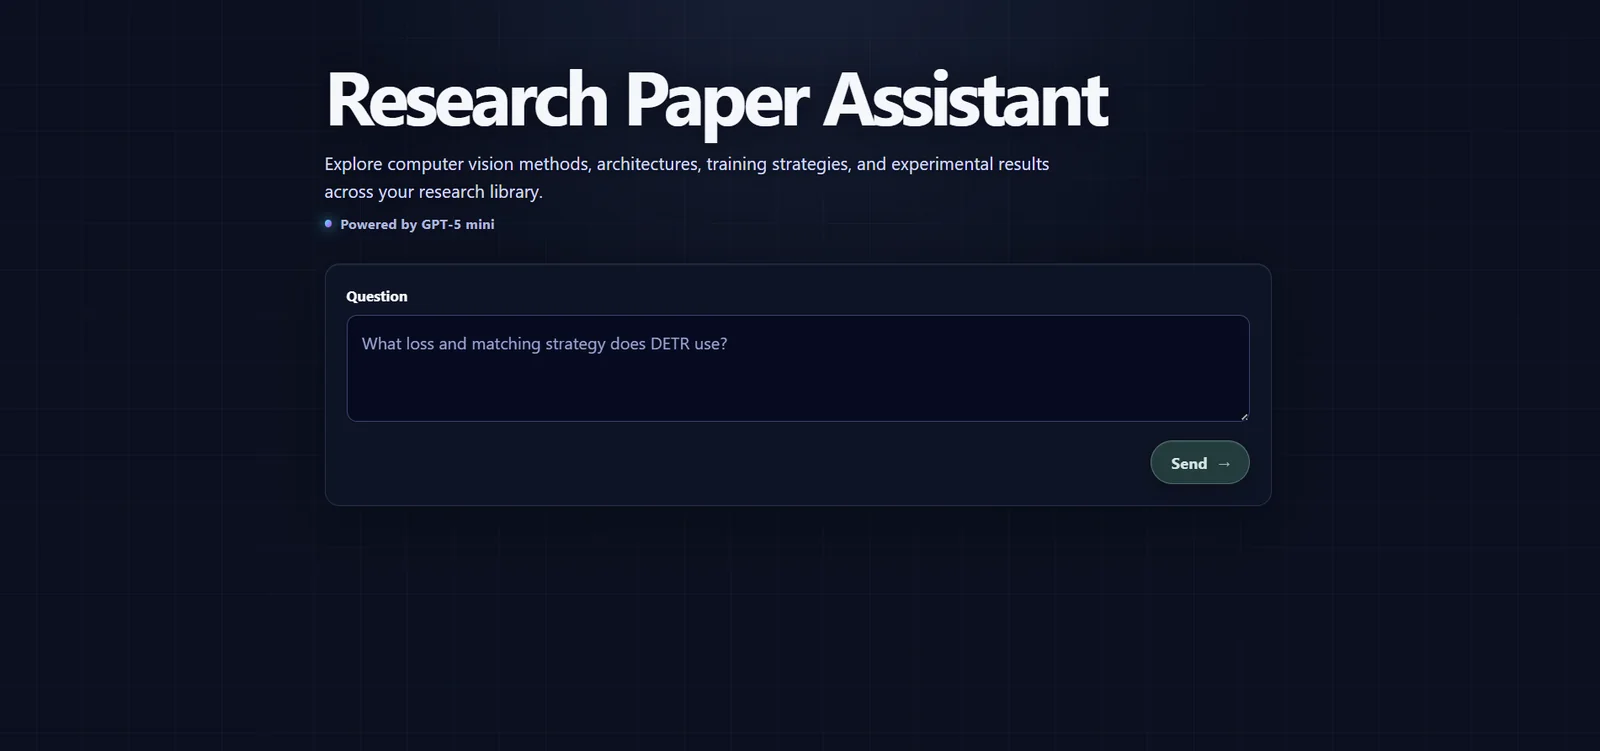
Question answering over a library of computer-vision papers, with structure-aware chunking, hybrid retrieval, reranking and answers that cite their sources.
- Role
- Developer
- Team
- Solo
- Status
- Runs locally
- Links
- Code ↗
Problem
- Papers break naive chunking: a fixed window cuts through equations, tables and figure captions, and the retrieved fragment then answers nothing.
- For research questions, a plausible answer is worthless without the passage it came from.
What I built
- PDF ingestion that follows document structure (sections, captions, references), so each chunk is a coherent piece of the paper.
- Hybrid retrieval combining embeddings with keyword search, which keeps exact terms like model and dataset names findable.
- Reranking on chunk metadata before the context is assembled, and answers returned with citations back to paper and section, served through FastAPI.
Key decisions
- Hybrid over embeddings-only retrieval: model names and metrics are the queries that matter most, and they're lexical.
- No answer without a citation. If retrieval comes back empty, the system says so.
Stack
- Python
- FastAPI
- Embeddings
- Hybrid retrieval
- ChromaDB
- PDF parsing